

 Contact Us
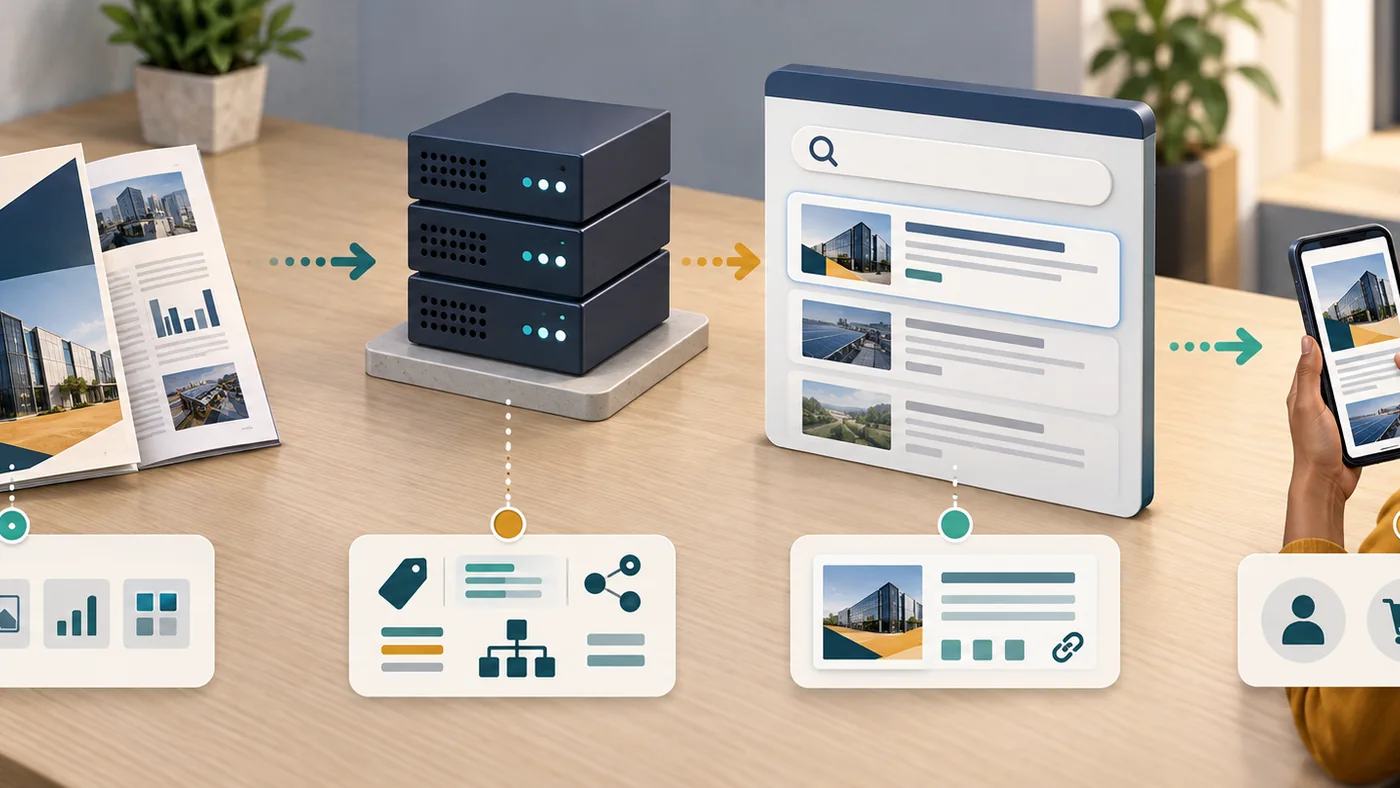
The direct answer: a PDF can appear in Google Search, but uploading a brochure or catalogue is not enough. The file needs a public, stable URL; an HTTP 200 response; extractable text; a clear document structure; a descriptive title; useful links; and an intentional indexing decision. If the same information also exists as an HTML page, choose which version should be canonical instead of leaving search engines to interpret two near-duplicates.
PDFs remain useful for Indian businesses. A manufacturer may need a downloadable technical catalogue. A real-estate firm may issue a project brochure. A consultancy may publish a research report, while a school, hospital or association may distribute forms and policies. The mistake is treating the PDF as a print file that happens to live online. Search engines, assistive technologies and mobile users encounter it as a digital document.
This guide shows how to decide whether PDF is the right format, prepare an accessible document, publish it with correct server controls and measure it honestly. It does not promise rankings. The objective is simpler: make an important business document understandable, discoverable and genuinely useful without weakening the rest of the website.
Can Google index PDFs?
Yes. Google lists Adobe Portable Document Format among the encoded file types it can index. Eligibility still depends on the basics: Googlebot must be able to reach the URL, the server should return a successful response, and the file must contain indexable content. Google’s technical requirements also make clear that meeting those minimum conditions does not guarantee indexing.
The practical question is not “Does Google support PDF?” It is “Can Google extract the meaning of this particular PDF, and should this file be the search result?” A well-formed report with real text, headings and links is very different from a stack of scanned pages saved as one enormous image. A password-protected document, a URL blocked from crawling, or a response that produces an error will also create obvious barriers.
A simple initial test is to open the document, select a sentence and paste it into a plain-text editor. If the words cannot be selected in a sensible order, the document may need optical character recognition and structural repair. That test is not a complete accessibility or indexing audit, but it quickly distinguishes a text document from an image-only scan.
Search visibility is not the same as a good search experience
A file may be indexable yet still disappoint a visitor. PDFs can be awkward on small screens, difficult to navigate, slow on weak mobile connections and disconnected from the surrounding website. They also provide fewer layout, interaction and analytics options than a normal page. An SEO review must therefore evaluate both machine access and the person who lands directly inside the file from search.
Choose HTML, PDF or both
Use PDF when the downloadable, fixed-layout document is the product: a printable specification, official report, signed policy, application form, price list or designed catalogue. Use HTML when the content must adapt fluidly to mobile screens, change frequently, support rich navigation, convert visitors through interactive elements or integrate tightly with the site.
| Publishing choice | Best suited to | Main SEO consideration |
|---|---|---|
| HTML page | Service explanations, product categories, evergreen guides and conversion pages | Usually the strongest format for mobile usability, internal linking, structured data and measurement. |
| PDF only | Formal documents whose fixed layout or offline use is essential | The file needs extractable text, document structure, a stable URL and a useful path back to the website. |
| HTML summary plus PDF | Reports, catalogues, brochures and research intended for both discovery and download | Give each version a distinct purpose or declare a canonical when the content is substantially duplicated. |
For many businesses, an HTML summary plus a PDF download is the most useful arrangement. The page can explain who the document is for, surface key findings, answer common questions and provide a clear enquiry path. The PDF can preserve the designed layout for printing, procurement reviews or offline sharing. This is not permission to create two identical versions without a plan.
Google supports a rel="canonical" HTTP response header for non-HTML documents. Its guidance on consolidating duplicate URLs specifically describes using a canonical header with PDF and other document formats. If an HTML page and PDF repeat essentially the same material, the PDF response can point to the preferred HTML URL. If the PDF contains the full original report and the page is only a distinct summary, both may provide independent value.
Do not choose a canonical simply because one format is newer or prettier. Decide which URL is the authoritative search destination, make internal links reinforce that decision, and keep the declared canonical stable. During a broader migration, include document URLs in the same redirect and canonical inventory used by the website redesign SEO checklist.
Build a searchable, accessible document
Good PDF SEO starts in the source document, not in the upload screen. Word processors, presentation tools and design applications can export files that look almost identical while carrying very different underlying structures. Build headings, paragraphs, lists, tables and links as real elements before export. Avoid positioning every line as an isolated text box simply to imitate print.
Use real text and repair scanned pages
Image-only scans need optical character recognition so words become searchable and selectable. OCR output must then be checked. Product codes, measurements, rupee values, proper names and mixed-language content are common error points. A visually perfect scan with inaccurate hidden text can mislead search systems and people using text-to-speech.
If an old catalogue contains hundreds of scanned pages, prioritise the sections that still serve customers. It may be better to rebuild current product families cleanly than to publish a poorly recognised archive. Retain the visual scan only when it has documentary value, and provide a usable text layer or accompanying HTML explanation.
Tag the structure and set the reading order
Headings should be marked as headings, lists as lists and tables as tables. Multi-column designs need a logical reading order so assistive technology does not jump between unrelated columns. Decorative graphics should not interrupt the content stream. Meaningful images, charts and diagrams need appropriate alternatives or nearby explanations.
The W3C’s current list of PDF accessibility techniques covers text alternatives, bookmarks, reading order, OCR, headings, links, form controls, document language and title metadata. Those techniques are informative examples rather than an automatic compliance certificate. They are still a valuable quality framework because they describe the structure real users need.
Add navigation for long documents
A 70-page report needs more than page numbers. Add bookmarks, a linked table of contents and descriptive link text. Repeat meaningful section headers where appropriate. Ensure the visible page numbering agrees with the document’s internal page labels, especially when preliminary pages use Roman numerals or the cover is unnumbered.
Set the document language and a descriptive document title. The filename, document title and visible heading should support the same subject without becoming identical strings stuffed with modifiers. Metadata can help software identify the file, but it cannot rescue thin, inaccurate or inaccessible content.
Design for phones as well as print
A4 pages packed with tiny type are hard to use on a phone. If mobile readers are important, choose a readable base size, avoid unnecessarily wide tables and test at realistic zoom levels. Use adequate contrast and do not convey meaning through colour alone. Compress photographs carefully, but keep diagrams and small labels legible.
Accessibility and responsive behaviour are not interchangeable. A tagged PDF can still force constant pinch-and-pan interaction, while a visually flexible file can still have a broken reading order. When mobile use is central to the task, publish the essential content in HTML and offer the PDF as a secondary download.
Optimise PDF content without keyword stuffing
Write the document for its actual reader. A machine-parts catalogue should help an engineer compare specifications. A financial report should make its reporting period and scope unmistakable. A school prospectus should answer admission questions. Search language belongs naturally in the title, opening summary, headings, captions and body only where it improves clarity.
Use one clear topic per document. A generic filename such as final-brochure-v7.pdf tells nobody what the file contains. A stable name such as industrial-water-pump-catalogue-2026.pdf is more useful in email, analytics, server logs and search results. Keep filenames lowercase, concise and hyphenated. Do not append dates or version numbers unless the distinction matters to users.
The first page should identify the organisation, document purpose, audience and edition. Add a short executive summary for long reports. Use descriptive headings instead of repeated slogans. If a chart contains a significant conclusion, explain it in nearby text rather than expecting a crawler or screen reader to infer the point from coloured bars.
Include useful, maintained links
PDF links should take readers to relevant product pages, service details, evidence, support and contact options. Use meaningful anchor text such as “request a technical assessment” instead of “click here.” Check links before every release. Unlike a web-page template, an old PDF can circulate for years after its links and prices have changed.
Keep the number of calls to action proportionate to the document. A technical report does not need a sales banner on every page. A catalogue should, however, make the next step obvious. If the document supports a complex project, link readers to the project enquiry page with enough context to understand what information to provide.
Publish with the right technical controls
Upload the final file to a public HTTPS URL under a logical directory. The server should return 200 OK and the correct application/pdf content type. Avoid temporary cloud-share URLs, expiring tokens and session-gated viewers for a document intended for organic discovery. A branded website URL is easier to maintain and trust.
Check the raw response, not only whether the file opens in your browser. Redirect chains, security middleware and download handlers can behave differently for crawlers. The diagnostic steps in the HTTP status code guide also apply to document URLs: a missing catalogue should not return a soft 404, and a replacement should receive one deliberate permanent redirect from the retired URL.
Control indexing with HTTP headers
A PDF cannot contain an HTML robots meta tag. To keep a public non-HTML resource out of search, Google documents the X-Robots-Tag response header. This is suitable for outdated price lists, duplicate print versions or documents that must remain publicly reachable but should not appear in search.
Do not rely on robots.txt as an indexing control. If crawling is blocked, Google may not see the noindex header. Allow the file to be fetched when you need a crawler to process that directive. Truly confidential information should never depend on search controls; protect it with authentication and correct access management.
Manage updates without creating URL clutter
For an annually distinct report, a dated URL can make sense because each edition has historical value. For a living product brochure, a stable evergreen URL may be better. When the URL changes, redirect the old address directly to the closest current equivalent. Do not leave several copies named “latest,” “final” and “final-new” accessible.
Large files also deserve a performance review. Remove unused embedded fonts, downsample oversized photographs and export graphics efficiently. Do not sacrifice legibility to reach an arbitrary file size. The earlier explanation of Googlebot file-size auditing distinguishes HTML limits from other resources and provides a useful reminder: measure the individual file and the actual delivery response instead of guessing from total page weight.
Help people and crawlers discover the PDF
A high-value PDF should not be an orphan. Link it from a relevant, crawlable HTML page using descriptive anchor text. For example, a pump manufacturer can link “download the 2026 industrial pump catalogue” from the matching product-family page. A research firm can link the complete report from an HTML summary that explains the methodology and main findings.
Internal links also transfer context. One strong link from the right service or resource page is more helpful than dozens of sitewide footer links. Include the canonical, indexable PDF in the XML sitemap when it is an important search destination, but remember that a sitemap is a discovery signal, not an indexing guarantee.
Review the surrounding page for conversion continuity. Someone entering through the PDF may never see the website navigation. Put the organisation name, website address and a suitable next action inside the document. For documents tied to a custom portal, catalogue or product system, a capable web development team should own the URL rules, headers, redirects and release checks instead of leaving them to manual uploads.
Measure what happens after publication
Use Search Console to inspect whether Google knows the URL, which queries expose it and whether the intended version is selected. Search operators can help with spot checks, but they are not a substitute for Search Console data. Record the publication date, URL, indexability decision, canonical target and responsible owner.
PDF measurement is often weaker than page analytics because the file may open directly in a browser or download outside the normal site session. Track clicks on download links from HTML pages, use consistent campaign parameters only when appropriate, and analyse server logs for requests. Do not present download counts as qualified leads unless the business has evidence connecting the two.
Monitor business outcomes that fit the document: catalogue enquiries, specification requests, report citations, form completions or assisted conversions. Compare by document edition and source. A sound technical SEO audit should identify broken delivery and discoverability, while content and sales teams decide whether the document actually helps its audience.
A practical catalogue example
Consider a hypothetical Delhi-based industrial equipment supplier. Its sales team distributes a 96-page catalogue by WhatsApp and email. The website links to three versions: catalogue-final.pdf, catalogue-new.pdf and a cloud-drive copy. All contain scanned product sheets. The text cannot be selected, links are printed but not clickable, and mobile users must zoom across dense landscape tables.
The company first decides what belongs in HTML. Product-family pages will carry current specifications, enquiry buttons and frequently changed availability. The PDF remains useful as an offline procurement reference. The team rebuilds the catalogue from structured source files, applies OCR only to historical certificates, tags headings and tables, sets reading order and language, adds bookmarks and writes a clear document title.
They publish the edition at one descriptive HTTPS URL and redirect the two obsolete site-hosted versions. The cloud-drive copy is removed from public promotion. A concise HTML catalogue page explains the document, highlights product families and links to the PDF. Because the page and file are complementary rather than duplicate, both remain indexable.
Before launch, the team checks the 200 response, content type, file size, selectable text, reading order, bookmarks, links, title, mobile view and enquiry path. It adds the HTML page and PDF to the appropriate crawl inventory, records the release in Search Console and measures downloads separately from enquiries. The company does not claim that the rewrite caused rankings or revenue until reliable data supports that conclusion.
This approach treats the catalogue as part of a customer journey, not as a forgotten attachment. Teams can review comparable standards of presentation and implementation in Web Solution Centre’s project portfolio.
Common PDF SEO mistakes
Publishing an image-only scan
A scan may look correct while providing no reliable text layer. Use OCR, verify its accuracy and rebuild structure where necessary. Do not assume an automated conversion understands columns, footnotes, specifications or bilingual text.
Using PDF for content that should be HTML
Service pages, changing price information and mobile-first conversion content usually belong on the website. PDF should serve a document need, not compensate for an inflexible CMS.
Leaving duplicate editions accessible
Multiple “final” files divide links, confuse customers and make updates risky. Choose a version strategy, redirect retired URLs and remove accidental public copies.
Blocking crawling when you need noindex
A blocked crawler cannot reliably process the file’s response headers. Use an accessible response with X-Robots-Tag: noindex for public files that should not appear in search, and use authentication for confidential material.
Forgetting people who enter through the document
A search visitor may never see the site header. Include the organisation, publication date, web address and a relevant next action inside the PDF. Keep those details maintained.
Compressing until the document becomes unreadable
Smaller is useful, but blurry diagrams and tiny labels destroy the document’s purpose. Remove waste first: oversized source images, unnecessary font subsets, hidden layers and duplicated assets.
Claiming SEO success from downloads alone
A download is an interaction, not proof of satisfaction or revenue. Combine search data, link-click tracking, server logs and genuine enquiry outcomes before drawing conclusions.
PDF SEO checklist for publication
- Confirm PDF is the right format, or pair it with a useful HTML summary.
- Use one clear search intent and audience for the document.
- Export real, selectable text; apply and verify OCR where required.
- Tag headings, paragraphs, lists, tables, figures and links correctly.
- Set a logical reading order, document language and descriptive title.
- Add bookmarks and a linked contents page to long documents.
- Write meaningful alternatives or explanations for informative visuals.
- Test contrast, font size, zoom behaviour and mobile readability.
- Use a short, descriptive, stable filename and HTTPS URL.
- Return HTTP 200 with the correct PDF content type.
- Choose a canonical strategy when HTML and PDF substantially duplicate each other.
- Use
X-Robots-Tagfor intentional non-HTML indexing controls. - Keep confidential documents behind real access controls.
- Compress images and fonts without harming legibility.
- Link the PDF from the most relevant crawlable page.
- Add useful links from the document back to maintained website destinations.
- Redirect retired document URLs directly to the best replacement.
- Include important canonical PDFs in the sitemap where appropriate.
- Validate the final public response, not only the local file.
- Record ownership, edition date and a review schedule.
- Measure search visibility, downloads and qualified outcomes separately.
Conclusion
PDF SEO is document publishing discipline. Google can index PDFs, but a useful result begins with more than a file extension. The document needs real text, clear structure, a stable public URL, accurate server controls, intentional canonicalisation and a path that helps readers complete their task.
Start with the format decision. If the content needs to adapt, convert and change often, publish it in HTML. If fixed layout and offline use matter, build the PDF as a digital document rather than a print export. When both formats serve the audience, give them distinct jobs and control duplication deliberately.
No checklist can guarantee that Google will index or rank a file, and an accessibility technique alone does not certify conformance. The defensible outcome is a document that people can read, navigate, verify and act on—and that search systems can fetch and understand without guesswork.
Sources
- Google Search Central: File types indexable by Google
- Google Search Central: Technical requirements
- Google Search Central: Canonicalisation and HTTP canonical headers
- Google Search Central: Robots meta tags and X-Robots-Tag
- Google Search Central: PDFs in Google search results
- W3C Web Accessibility Initiative: PDF techniques for WCAG
- W3C Web Accessibility Initiative: About WCAG techniques