

 Contact Us
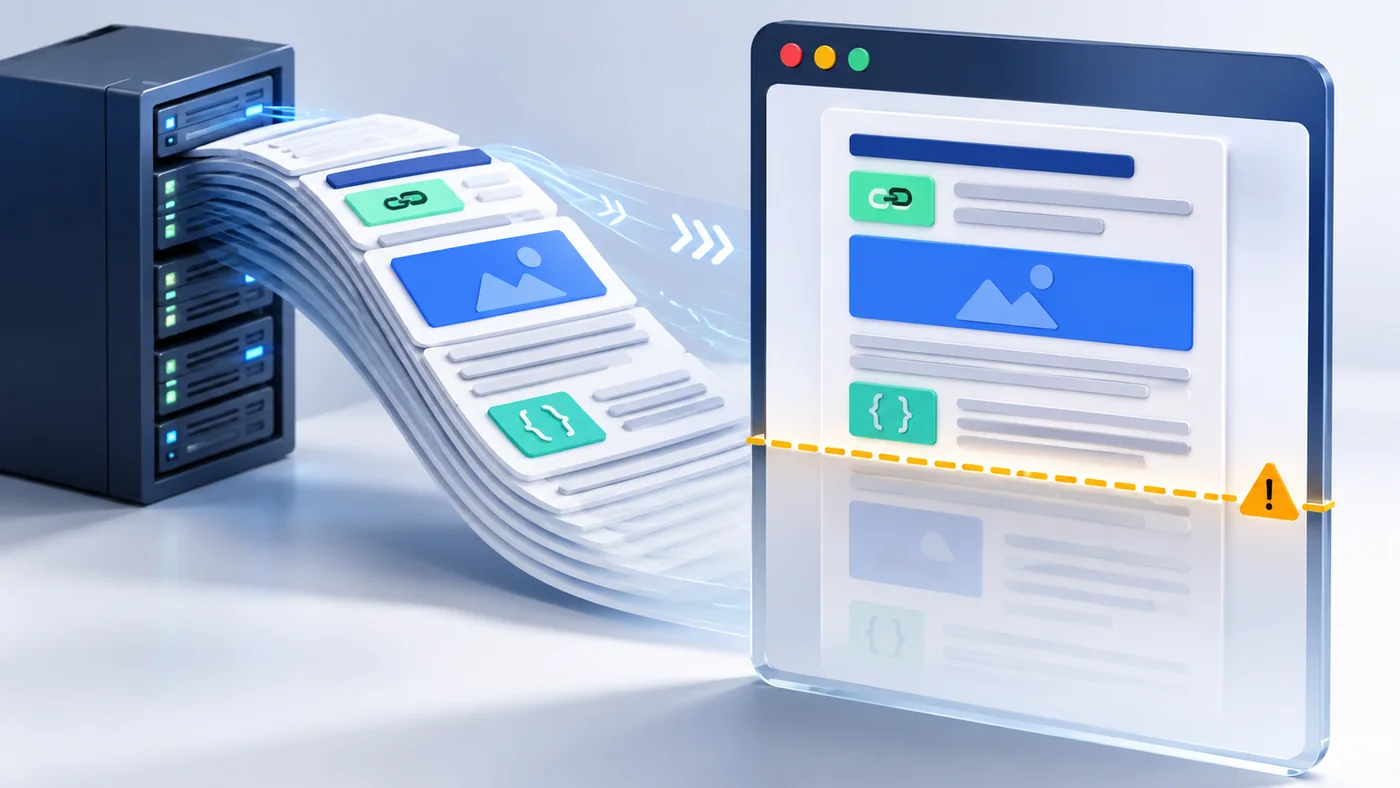
The direct answer: Googlebot currently fetches only the first 2 MB of a supported file, measured on the uncompressed response and including the HTTP headers. If an HTML document crosses that boundary, Google does not reject the URL; it stops fetching and sends only the portion it received for rendering and indexing consideration. Content, links, canonical tags, structured data or scripts placed after the cutoff may therefore be invisible to Google.
Most business pages are nowhere near 2 MB of HTML, so this is not a reason to panic or impose an arbitrary minimalist design. It is a reason to measure. Oversized source documents do appear on ecommerce catalogues, JavaScript applications, page-builder templates, personalised portals and sites that embed images or large data objects directly in the markup. A page can also look fast in a browser because compression and caching help the visitor while its uncompressed HTML remains surprisingly large.
This guide explains what the limit includes, who is genuinely at risk, how to audit representative templates and how to fix the source of bloat without stripping useful content. The goal is not to promise rankings. It is to ensure that search systems can retrieve the same important page signals that customers can see.
What Googlebot’s 2 MB limit actually means
Google clarified the mechanics in its 2026 explanation of how its crawling infrastructure processes bytes. For a normal supported file, Googlebot fetches up to 2 MB. PDFs have a separate 64 MB limit, and other Google crawlers can use different thresholds. Once Googlebot reaches its limit, the remaining bytes are not fetched, rendered or indexed.
Four details matter in practice:
- The limit is per fetched resource. The HTML document has its own allowance. A linked CSS or JavaScript file is fetched separately and is subject to the relevant per-resource limit.
- The limit applies to uncompressed data. Brotli or gzip can reduce bytes transferred over the network, but compression does not turn 2.4 MB of decoded HTML into a safe 300 KB document for this calculation.
- HTTP headers count. Large cookie-related or application headers consume some of the available response before the document body.
- The cutoff is not an indexing penalty. Google processes the portion it received. The risk is that something important is located in the portion it did not receive.
The current Googlebot documentation confirms that the first 2 MB of a supported file is crawled and that the size is assessed after decompression. This is important because the “Transferred” figure in a browser network panel may show a much smaller compressed payload than the actual resource size.
Two megabytes of HTML is not two megabytes for the whole page
A modern product page may download images, fonts, CSS, JavaScript and API responses whose combined weight is much larger than 2 MB. That total page weight is a performance concern, but it is not the same measurement. The SEO fetch risk discussed here concerns each individual resource, especially the initial HTML response. A 4 MB hero photograph referenced through an image URL does not count toward the HTML document’s 2 MB body. The same photograph embedded as a base64 data URI inside the HTML does.
The first 2 MB is treated as the available document
The cutoff can create an incomplete but superficially valid document. Imagine an opening tag that starts before the boundary while its closing tag, primary copy and internal links fall after it. Google’s Web Rendering Service receives only what the crawler fetched. It cannot execute a script or interpret markup that never arrived.
Google’s JavaScript SEO guidance describes crawling, rendering and indexing as connected stages. Server-side or pre-rendering can make content easier for both people and crawlers, but it does not excuse an oversized initial response. The renderer can work only with the HTML and referenced resources that were successfully retrieved.
Why HTML documents become oversized
Long articles rarely cause the problem on their own. Three thousand words of clean text occupy only a small fraction of 2 MB. Oversized documents usually come from implementation decisions that replicate or encode far more data than the visible page needs.
| Source of growth | What it looks like | Likely remedy |
|---|---|---|
| Base64 media | Images, icons or fonts embedded as long data strings in markup or styles | Serve cacheable files through normal URLs. |
| Inline CSS and JavaScript | Large style sheets, libraries or application bundles repeated on every response | Move stable code to versioned external files. |
| Hydration state | Large JSON objects containing full catalogues, filters, translations or duplicated records | Serialize only data required for the first view; fetch the rest when needed. |
| Mega-navigation | Thousands of repeated links, hidden panels and deeply nested mobile/desktop variants | Simplify information architecture and render one accessible navigation system. |
| Page-builder markup | Deep wrapper nesting, duplicated components and verbose inline settings | Refactor high-traffic templates and remove unused modules. |
| Third-party snippets | Multiple tag managers, duplicated widgets or vendor configuration placed inline | Audit ownership, necessity and loading strategy. |
| Personalisation payloads | Large user, location or pricing objects included before they are required | Keep cacheable public HTML lean and load private data deliberately. |
Markup depth can also affect the browser even when byte size stays below Googlebot’s limit. Chrome’s guidance on DOM size and interactivity explains that a large DOM can increase style recalculation and layout work. The two audits should inform each other: source bytes reveal what the server sends, while DOM inspection reveals what the browser builds after scripts run.
Template multiplication makes one defect expensive
Teams planning a rebuild should add HTML-size checks to the same controls used for redirects, canonical tags and release readiness. The broader website redesign SEO checklist can help place this audit inside a migration process rather than treating it as an isolated optimisation.
Which websites should investigate first
Every site can record document size, but not every site needs an emergency project. Prioritise investigation when one or more of these conditions are present:
- HTML responses routinely exceed 1 MB before compression or vary sharply between otherwise similar pages.
- Critical copy, canonicals or structured data appear late in “view source.”
- Product or directory pages embed large JSON catalogues for client-side filtering.
- The CMS outputs base64 images, fonts or icons into each page.
- Mobile and desktop menus are duplicated in the document rather than progressively enhanced.
- Google’s inspected HTML is missing content that is visible in a normal browser.
- A recent design-system, framework or tag-manager release caused document size to jump across a template.
Small brochure sites with clean server-rendered pages will usually have ample headroom. Large inventory sites, news platforms, marketplaces and highly customised single-page applications deserve stronger automated controls. If your team cannot determine which templates create the problem, a focused SEO audit should trace the byte growth to components and release changes rather than return a generic “reduce page size” recommendation.
A practical HTML-size audit workflow
The audit should reproduce the public response, measure the right bytes, locate important elements and compare what Google can render. Do it first in a staging environment when fixes could affect templates or application state.
1. Build a representative URL sample
Choose examples from every important template: homepage, service page, article, product, category, search result, location page, paginated listing and any personalised or logged-out variation. Include both short and content-heavy records. Add URLs flagged in Search Console and URLs changed by recent releases.
Record the template, HTTP status, content type, declared encoding, compressed transfer size, uncompressed body size and final canonical. This turns a one-off check into a baseline that can be repeated after a deployment.
2. Measure the uncompressed response body
A command-line request is useful because it can explicitly ask for an identity-encoded response and save the body for inspection:
curl -sS -H "Accept-Encoding: identity" -D response-headers.txt \
  -o page.html "https://example.com/category"
wc -c page.html
The body count is a practical approximation, not a perfect simulation, because Google also counts response headers. Inspect response-headers.txt and investigate unusually large headers rather than treating exactly 2,000,000 body bytes as a safe target. Leave comfortable headroom for dynamic values and future components.
On Windows, PowerShell or a developer tool can save the response and report its byte length. Whichever method you use, do not rely only on the visually rendered page or the compressed “Transferred” column.
3. Locate critical signals in raw source
Search the saved HTML for the title, meta description, robots directive, canonical, hreflang annotations where relevant, main heading, primary content, essential internal links and JSON-LD. Record roughly where each begins in the byte stream. An element can be present in the full file yet unsafe if it is located after the crawler’s fetch boundary.
You can create a diagnostic copy of the first portion of the body and search that copy for the same signals. Remember that this is a conservative engineering check, not proof of Google’s exact request, because headers, content negotiation and dynamic output can differ.
4. Compare initial and rendered HTML
Use Search Console’s URL Inspection tool or the Rich Results Test to review what Google received and rendered. Google’s troubleshooting guide recommends these tools for checking loaded resources, JavaScript errors and rendered HTML. If raw source contains the main content but the rendered version does not, the issue may be JavaScript execution or resource access. If the content is already beyond the fetch boundary, rendering cannot recover it.
The site’s JavaScript SEO implementation should be reviewed separately when client-side routing, app shells or API failures are involved. Do not label every missing element as a byte-limit problem merely because the page is large.
5. Inspect components and server logs
Break the document into accountable pieces: global header, navigation, styles, scripts, application state, body content, recommendations, footer and third-party code. Measure which block contributes the most. Then compare server logs and release history. A size jump that begins on one deployment date usually has a more precise cause than a long-standing template pattern.
6. Add a regression budget
After remediation, add a build or monitoring threshold well below the hard limit. The correct threshold depends on the product, but a warning based on the team’s healthy baseline is more useful than waiting for 2 MB. For example, if a product template normally produces 180 KB of HTML, a sudden move to 500 KB deserves review even though it is not near Googlebot’s cutoff.
Track the median and upper percentile for each template family. A single global average can hide rare but valuable pages whose variants include far larger menus, specifications or application state.
How to reduce HTML safely
Start with the largest avoidable block, not cosmetic minification. Removing whitespace may save a modest amount; extracting a 1.2 MB base64 image or duplicated catalogue object changes the risk immediately.
Serve binary assets as files
Move embedded images, fonts and reusable icons to normal URLs so they can be cached and fetched independently. Use modern formats, responsive image markup and descriptive alt text. The aim is not merely smaller HTML: it also gives browsers and crawlers clearer resource boundaries.
Externalise stable code
Large inline style sheets and scripts repeated on every page inflate every response. Put stable, reusable code in versioned external files. Keep only genuinely critical, small fragments inline when there is a tested performance reason. Coordinate this with the web development team, because extracting code can affect loading order, caching and layout.
Shrink hydration and state payloads
Client-rendered applications often serialize server data into the HTML so the browser can resume the page. Audit that object field by field. Do not ship an entire product catalogue, every locale, unused CMS fields or repeated descriptions when the first view needs only a small subset. Paginate or request secondary data through stable endpoints after the primary page is usable.
Be careful: deleting state without understanding the framework can cause hydration mismatches or visible regressions. Create automated tests for the page’s primary actions and compare both source and rendered output.
Simplify navigation without hiding important links
A mega-menu should help people understand the site, but it should not reproduce thousands of URLs in multiple hidden desktop and mobile trees. Consolidate duplicate markup, use a logical hierarchy and retain crawlable HTML links for important destinations. The objective is a smaller, clearer navigation system, not a JavaScript-only menu that search systems or keyboard users cannot operate.
Remove orphaned vendor code
Third-party widgets often outlive the campaign or employee who installed them. Inventory each inline snippet and configuration blob. Identify its owner, business purpose, privacy implications and loading condition. Remove duplicates and expired tools through normal change control. A tag-manager container does not make code free; it only changes where responsibility is visible.
Improve server health as a separate control
Smaller documents can be cheaper to generate and transfer, but crawl capacity also depends on server responsiveness and errors. Google’s updated crawl-budget guidance says most sites do not need advanced crawl-budget work, while very large or rapidly changing sites should monitor crawl health, inventory and serving capacity. Do not sell an HTML reduction as a guaranteed way to “increase crawl budget.”
Why source order is a safety control
Reducing the document below an internal budget is the durable fix. Source order provides defence in depth. Place essential head elements early: character encoding, viewport, title, robots instructions, canonical, relevant alternate links and necessary structured data. Deliver the main heading and primary content before large optional widgets, recommendation carousels and footers.
This does not mean stuffing every SEO element into the first line or duplicating metadata. It means the document should communicate its identity and purpose before optional decoration. Google’s official 2026 guidance specifically recommends placing critical metadata and structured data higher in the HTML so they are unlikely to fall beyond the cutoff.
Structured data must still match visible content and follow Google’s general structured data guidelines. Moving incorrect markup earlier does not make it eligible for a rich result. Accuracy, relevance and technical accessibility all remain necessary.
A realistic ecommerce example
Consider a hypothetical Indian home-furnishing retailer with 18,000 product URLs. Its category pages look normal and transfer about 420 KB over a compressed connection. A developer measures the decoded HTML and finds that some categories produce 2.35 MB. The visible product grid begins early, so manual checks have never exposed an obvious problem.
Component analysis finds three causes: a 900 KB base64 font embedded by a page-builder block, 760 KB of filter and inventory data serialized for products not shown on the first page, and duplicated desktop and mobile navigation. The canonical and ItemList structured data are generated near the end of the head and body respectively. On the largest categories, one or both can fall outside a conservative first-2-MB diagnostic copy.
The team does not delete product descriptions or remove useful filters. It serves the font as a cacheable file, limits the initial state to the visible products and current filter values, requests later results when users paginate, and renders one accessible navigation structure. It moves the canonical and essential JSON-LD earlier, then tests category, pagination and filtered states.
After deployment, the team verifies HTTP responses, raw HTML, rendered HTML, canonical selection, structured-data validity, filter usability and document-size monitoring. The resulting pages have more headroom, but the team does not claim an organic-traffic uplift before evidence exists. It records the change date and watches Search Console and analytics over an appropriate period.
This is the standard to expect from technical work: a measurable defect, a scoped remedy, preserved customer value and honest reporting. Examples of broader implementation quality can be reviewed in Web Solution Centre’s project portfolio.
Common mistakes
Confusing compressed transfer size with decoded size
A 300 KB network transfer can expand into more than 2 MB after decompression. Record both measurements and label them clearly. Compression remains valuable for users and bandwidth, but it does not change the documented uncompressed cutoff.
Optimising total page weight instead of the HTML resource
Images and video often dominate total page weight. Optimise them for performance, but do not assume they consume the initial document’s allowance when referenced as separate files. Find the large individual resource before choosing a remedy.
Removing useful content to hit a number
Human-readable specifications, policies, comparisons and supporting copy rarely explain megabytes of markup. Remove technical duplication before editorial value. People-first content should not become collateral damage for a problem caused by embedded media or excessive application state.
Treating 2 MB as a recommended target
The limit is a ceiling, not a design budget. A page at 1.99 MB has little resilience for headers, personalisation, experiments or future components. Set template thresholds from healthy baselines and investigate meaningful growth early.
Testing only one URL
The homepage may be small while categories, articles or locations use different templates. Sample each page family, including outliers with the largest menus, data sets or descriptions.
Moving everything higher without reducing anything
Source order can protect critical signals, but it does not solve bandwidth, rendering or maintainability. It also cannot save essential body content if the document remains chronically oversized. Reduce the cause and use ordering as a secondary safeguard.
Deploying framework changes without functional QA
Removing hydration data or consolidating components can break filters, carts, language selectors and analytics. Test business-critical flows, accessibility, mobile layouts and rendered content before and after release. For a production review, discuss the affected templates and evidence with the team through the project enquiry page.
Googlebot HTML-size implementation checklist
- Confirm the final URL returns the intended status and HTML content type.
- Measure uncompressed response-body bytes for every important template.
- Inspect response headers and leave headroom below the documented limit.
- Record compressed and uncompressed sizes separately.
- Search raw source for title, robots, canonical, structured data, H1, primary copy and internal links.
- Compare initial source with Google’s rendered HTML.
- Check whether base64 media, inline bundles or oversized state objects dominate the response.
- Verify navigation remains accessible and crawlable after consolidation.
- Test structured data against visible content and current policies.
- Test product, filter, form, checkout and other critical interactions after code changes.
- Re-crawl a representative URL set and compare measurements with the baseline.
- Add template-level monitoring or CI warnings for unexpected HTML growth.
- Record the release date and observe Search Console without promising a ranking outcome.
Conclusion
Googlebot’s 2 MB HTML limit is easy to misunderstand because a browser may display an oversized page and network compression may make the transfer look modest. The practical rule is simple: measure the uncompressed HTML response, identify where critical elements occur, and remove avoidable bytes from the template before the page approaches the cutoff.
For most small business websites, this check will confirm that there is no problem. For large ecommerce, directory and JavaScript-driven sites, it can reveal a quiet failure mode that ordinary visual QA misses. Fix the largest technical source first, keep essential signals and primary content early, test the rendered result, and add regression monitoring so the same bloat does not return.
A leaner document is not a ranking guarantee. It is sound engineering: the crawler receives a complete page, the browser has less unnecessary work, and the team gains a measurable boundary for future releases.
Sources
- Google Search Central: Inside Googlebot—crawling, fetching and byte limits
- Google Search Central: Googlebot technical properties and file-size limits
- Google Search Central: JavaScript SEO basics
- Google Search Central: General structured data guidelines
- Google Crawling Infrastructure: Crawl budget guidance
- web.dev: How large DOM sizes affect interactivity